Mattias Seger, with research and drafting support from Claude · 5 November 2026
Every function hit its target, and the customer still waited.
Four habits are at the end, to use before you lock your 2027 targets.
Two good plans and a corridor
Every autumn at a large retail group I worked with for several years, the numbers arrived in the same order: group, function, region, store. The CFO, Magnus, had built the model years earlier, and it had served the company well. Growth came and margins held. Nobody wanted to be the person who questioned the thing that worked.
The planning day I remember best went like this. The head of one function presented a plan that would hit her number. The head of the next presented a plan that would hit his. Both were good plans, and both were approved. Her plan made his harder. Nobody said so in the room, because nobody had been given the number that sat between them, so nobody had to answer for it.
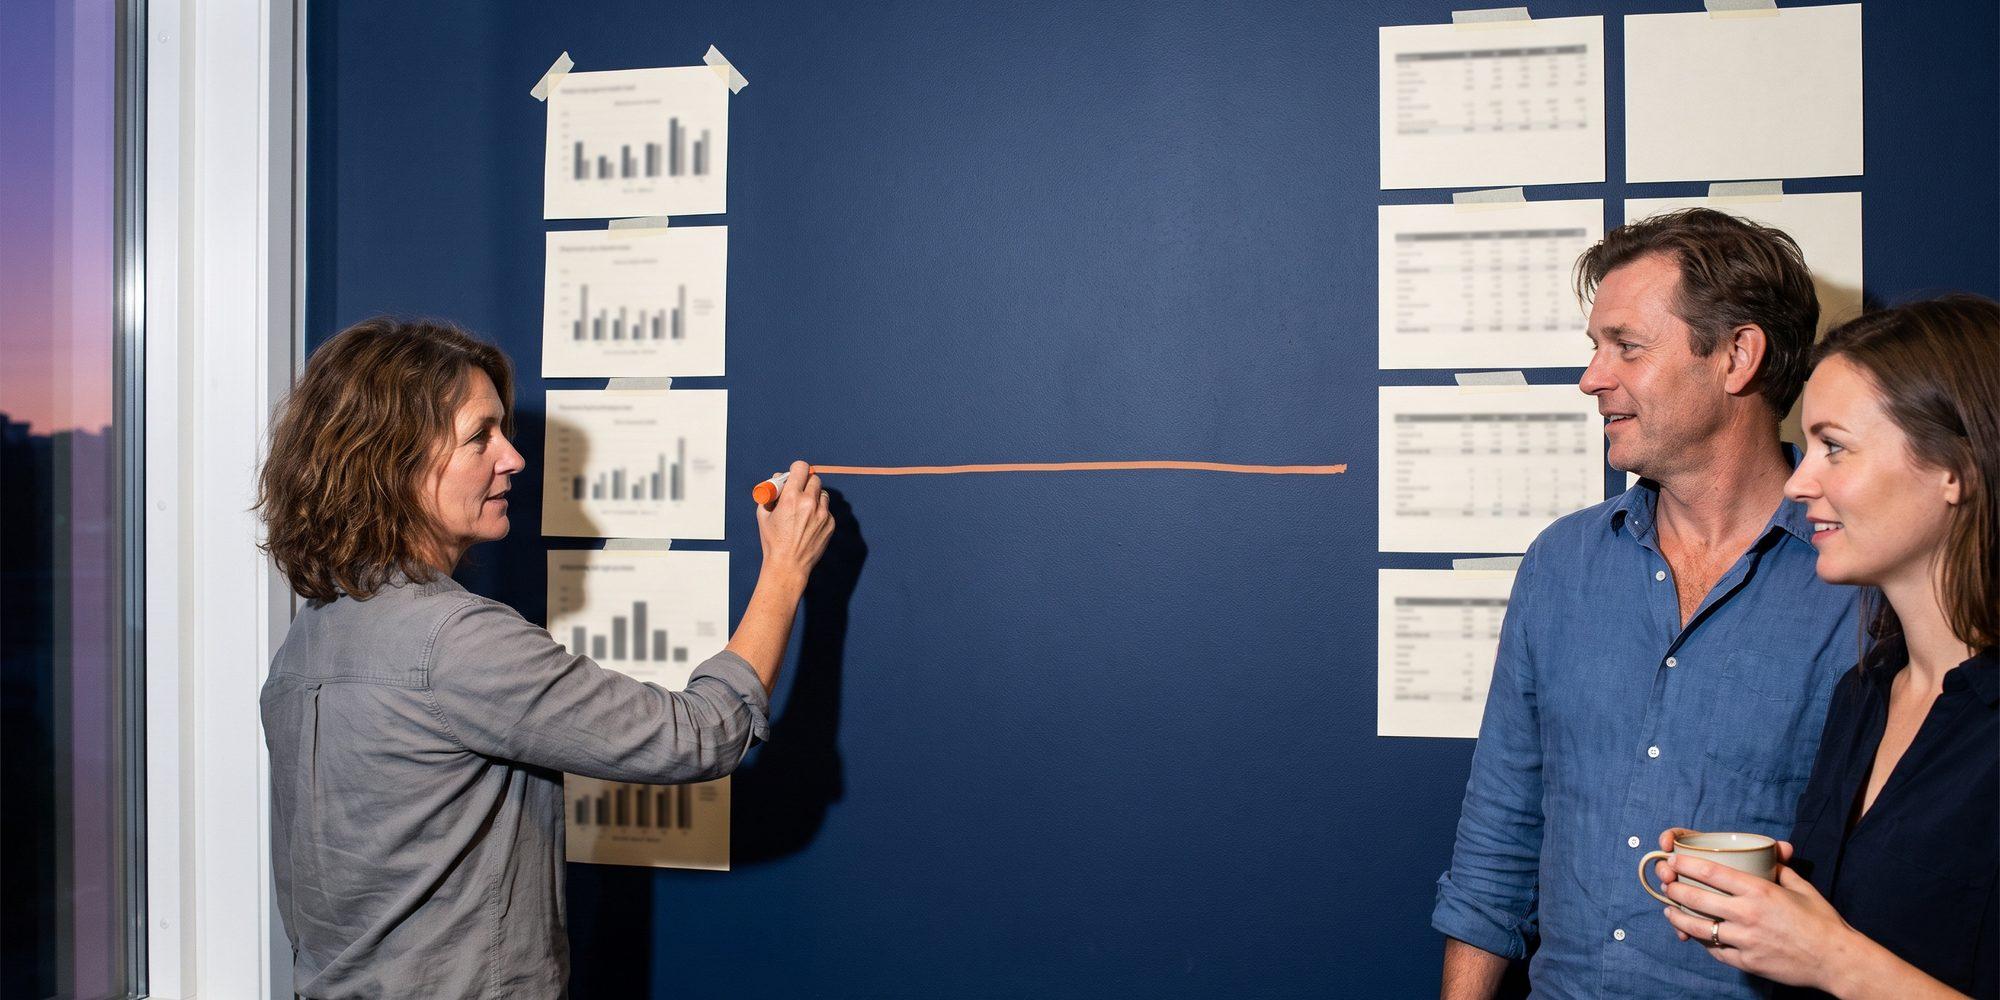
I noticed. I said it afterwards, in the corridor, to two people who agreed with me. The following year I said it in the corridor again. I should have said it at the wall, with a marker in my hand.
The organisations in this series are composites from my work since 2012. People and details are changed.
What happens when agents work to your targets
Many large companies lock their 2027 targets this month, in rooms much like that one. At Enterprise Movement we run our own company AI-native, on Scaled Agile’s AI-Native SAFe: people lead on outcomes, agents do the output. So I have started to look at that planning day with a new question. What happens when the work towards those targets is done by agents?
In the first article of this series I argued that AI speeds up the organisation you already have. A team pursues its number with some friction. People talk in corridors, notice when a colleague’s queue grows, and quietly bend the plan. An agent given a department’s number and good context pursues it without that friction. It is faster and more literal.
If the number is local, you get the old silo, only faster. And the corridor conversation that used to soften it no longer happens.
The number between
I call it the number between: a result a customer would notice, which depends on two or more functions and appears in nobody’s targets. In a retailer it is the online order that is ready on time. In a public agency it is the case that moves from one unit to the next without waiting. In a manufacturer it is the delivery date that sales promised and production has to keep.
A linear goal cascade cannot see it. Its logic is that if every box hits its part, the whole adds up. That holds when value is created inside the boxes. In my experience it is created between them, which is where the customer stands.
At the retailer, the cascade gave every function a reason to optimise its own number and nobody a reason to own the handovers. Another KPI on Magnus’s dashboard would not have changed that.
Why agents will optimise it away
Economists described this pattern long before agents. In 1991 Bengt Holmström and Paul Milgrom showed that when a job has several dimensions and only some are measured, effort rationally shifts towards the measured ones.
Goal-setting research found the same pattern in practice. In Goals Gone Wild (2009), Lisa Ordóñez, Maurice Schweitzer, Adam Galinsky and Max Bazerman showed that narrow goals have systematic side effects: focus on one area at the expense of others, distorted risk-taking and, at worst, unethical shortcuts. Their best-known example is the Ford Pinto, built to a target of under 2,000 pounds and under 2,000 dollars. The goal crowded out safety.
In March 2026 Jiacheng Wang and Jinbin Huang built on Holmström and Milgrom’s model to analyse AI agents. Their work is theoretical, not empirical, but the conclusion is blunt. An optimised agent systematically under-invests in the quality dimensions its evaluation does not cover, and they treat this as a structural equilibrium rather than a bug to be fixed. The more tools an agent has, the smaller the share of its work a finite evaluation can cover.
In a goal cascade, the number between is by design the dimension no department is evaluated on. A human team neglects it a little. Wang and Huang’s model gives no reason to expect an agent to neglect it less, and the corridor that softened it for people is gone.
In Systemic Actions, my book series whose first volume, Seeing the Whole, is out on 19 January 2027, I treat goals, and how they are broken down, as one of five conditions that shape behaviour in an organisation. Donella Meadows ranked the places to intervene in a system and put numbers and parameters near the bottom and the goals of the system near the top. Splitting one number into smaller numbers is work at the bottom of her list. Naming the number between and giving it an owner is work higher up, and no leader can do that from inside their own box.
The same agents can carry the evidence up
In our implementation of AI-Native SAFe we use a different structure: an outcome tree, where every target sits above the work that serves it. Portfolio outcomes sit at the top, then the outcomes of each Agile Release Train (a standing team of teams around one value stream), then each planning interval (about a quarter), then team commitments. Every node carries key results and the evidence for them. The number between finally gets an address: a node that several functions serve together.
Agents assemble the evidence up the tree every week. The Monday slide deck mostly gives way to a weekly Sense and Respond, and every decision, including a decision to stop, is recorded as a change to the tree. Mik Kersten makes a related case in Output to Outcome (IT Revolution, 2026). As AI makes knowledge work more productive, he argues, the bottleneck moves to the operating model, and organisations have to align people and agents around measurable customer and business outcomes.
The survey data points the same way, though it does not prove the case. In McKinsey’s The state of AI in 2026 (1,719 respondents), about 6% were high performers, and nearly three in four of them had fundamentally redesigned workflows, against about one in four of the rest.
I offer the tree as a design, drawn from how we run our own company. It has limits. An agent that assembles evidence for a target it also pursues is grading its own work, so the people at the gates need the raw data, not only the summary. The tree also inherits its top node: an untested target at the top spreads its error down every branch, faster than a cascade did. And a shared node means each function gives up some control over its own number. That is a question of power, and it lands on the executive team.
Four habits for your 2027 targets
Here is what would have had to be true on that planning day. Each habit is small enough to start this month.
1. Name the number between before you split anything. For each target, ask which other function’s number has to move for yours to move. Write the shared result above both, in words a customer would recognise.
Before: Region West: +8% sales.
After: Shared with Supply: 95% of online orders ready for pickup within two hours. Region West’s +8% depends on it.
2. Accept no target without an evidence path. A target enters the tree only when someone can say what evidence comes back up, how often, and who reads it. At a logistics company I worked with, a regional head set a target to double revenue. Nobody questioned it; the cascade simply divided it. Asking for the evidence path would have tested it at the first gate.
Before: Double revenue by 2028.
After: Double revenue by 2028. Evidence: margin per customer segment, assembled monthly by an agent and read by the portfolio owner every iteration.
3. Tell every agent what it must not sacrifice. An agent optimises what it is evaluated on. Put the number between into that evaluation as a guardrail beside its local target.
Before: Maximise conversion in the web shop.
After: Maximise conversion without letting pickup readiness fall below 95% or returns rise above today’s level.
4. Fund the outcome, and budget the judgement. If you change how targets are broken down and leave the money alone, the money wins. Ring-fence one envelope for one value stream. Fund its outcomes for one planning interval instead of a list of projects, and re-point the money when the evidence changes. Budget the hours of the people who must say yes at the gates as explicitly as you budget tokens. My colleague Ola Gedenryd calls judgement capacity “the constraint you will hit first”.
Before: Q1 budget: projects A, B and C.
After: Q1 envelope: the online-pickup value stream, kept or stopped at each iteration review, with judgement hours from the business owner booked every week.
Bring the controllers in to design that envelope, not to approve it afterwards. Capitalisation, cost allocation across legal entities and quarterly reporting are real questions with real rules. And invite the person who built the current model. Magnus was its most credible defender. He would also have been its best redesigner, because he knew exactly which parts carried weight.
The before-and-after targets are illustrations, not client data.
Say it at the wall
I still think about that corridor. Several of us could see the number between that day. We had the data. We had no place to put the number, and nobody whose job it was to say it out loud. Agents can carry the evidence. Only people can stand at the wall and draw the first line between two columns.
One hour before Friday 13 November
This week’s Systemic Action: book one hour with your CFO or group controller. Bring one 2027 target and ask each other: which other function’s number has to move for ours to move?
If the answer is that nobody owns it, that is where we start. At Enterprise Movement we work through these questions with executive teams. Book a free 30‑minute conversation. No pitch deck: bring one target and the function it depends on.
Research and drafting were supported by AI, and the photograph at the top is AI-generated. The experiences and interpretations are my own, and I have reviewed and take responsibility for every claim. The cases are composites; the AI-native parts describe a design drawn from how we run Enterprise Movement.
References
- Holmström, B. and Milgrom, P. (1991). Multitask principal–agent analyses: Incentive contracts, asset ownership, and job design. Journal of Law, Economics, & Organization, 7, 24–52.
- Wang, J. and Huang, J. (2026). Reward hacking as equilibrium under finite evaluation. arXiv:2603.28063.
- Ordóñez, L. D., Schweitzer, M. E., Galinsky, A. D. and Bazerman, M. H. (2009). Goals gone wild: The systematic side effects of overprescribing goal setting. Academy of Management Perspectives, 23(1). Summary: HBS Working Knowledge.
- Meadows, D. (1999). Leverage Points: Places to Intervene in a System. Sustainability Institute.
- Kersten, M. (2026). Output to Outcome: An Operating Model for the Age of AI. IT Revolution.
- McKinsey & Company (2026). The state of AI in 2026: On the road to ROI. 25 August 2026; 1,719 respondents.
- Scaled Agile. ART Sense and Respond, AI-Native SAFe.
- Gedenryd, O. (2026). We Run Our Whole Business on AI-Native SAFe. Enterprise Movement, 21 August 2026.